Key Takeaways
- The best PII redaction tool isn’t the one that detects the most patterns. It’s the one that understands context.
- As AI adoption grows, PII redaction has evolved from a compliance feature into a core layer of AI security.
- Different redaction tools solve different problems. The right choice depends on your workflows, data types, and deployment needs.
- Protecting sensitive data is no longer enough. Modern redaction solutions must preserve usability while keeping information secure.
An executive whitepaper on how AI-Native DLP differs from legacy DLP, and what it means for enterprise security strategy.
Download WhitepaperBest PII Redaction Tools in 2026: Features, Pricing & Comparison
Our increasingly data-centric world demands stronger protection for sensitive information and Personally Identifiable Information (PII).
In our recent conversations, we have seen enterprises move towards visibility and observability to monitor employee AI usage. But as organizations go beyond monitoring, equipping employees with built-in redaction tools for top LLMs such as ChatGPT, Claude, and Gemini has become a must-have.
Traditional redaction tools often over-redact or under-redact, either risking the loss of context or allowing sensitive data to slip through, leading to potential compliance violations.
In contrast, the latest PII redaction tools have cracked the code on moving past these limitations, helping organizations automatically detect and remove sensitive information before it's stored, shared, or processed by downstream applications.
From protecting customer conversations to securing AI workflows, these tools reduce the risk of data exposure while helping organizations comply with privacy regulations such as GDPR and HIPAA.
In this guide, we compare four such PII redaction tools: Wald, Private AI, Redactable, and AssemblyAI. We'll explore their key features, ease of use, performance, deployment options, pricing models, and ideal use cases to help you select the right solution for your organization's data protection needs.
What is the Best PII Redaction Tool?
Picking the best PII Redaction tool is completely subjective to your organization's use case. Enterprise teams often prioritize deployment flexibility, compliance capabilities, and contextual accuracy, while developers may prefer API-first platforms that integrate easily into existing workflows.
Organizations focused on document workflows may benefit from dedicated PDF redaction software, whereas those processing speech data require real-time transcription and audio redaction capabilities.
What is PII Redaction?
Personally Identifiable Information (PII) redaction is the process of identifying and removing, masking, or replacing information that can be used to identify an individual. Common examples include names, email addresses, phone numbers, government-issued identification numbers, payment information, and other sensitive personal data.
Traditional redaction often relied on manual review or regular expressions (regex) to detect predefined patterns. Modern AI-powered PII redaction tools combine machine learning and natural language processing (NLP) to identify sensitive information across structured and unstructured data with greater accuracy. They can automatically redact PII from documents, PDFs, emails, chat conversations, audio transcripts, and AI prompts while preserving the usefulness of the remaining content.
Why Context Matters in PII Redaction
Not all sensitive information follows a fixed pattern. While regex-based detection works well for structured data like credit card numbers or email addresses, it often struggles to identify information whose sensitivity depends on context.
For example, the name "Jordan" could refer to a customer, an employee, a country, or a product name. Context-aware AI models analyze surrounding words and sentence structure to determine whether information should be redacted, helping reduce false positives (redacting information that isn't sensitive) and false negatives (missing information that should have been protected).
AI applications also frequently process long-form, unstructured conversations where sensitive information isn't always predictable, making contextual detection more effective than relying solely on predefined patterns.
PII vs PHI vs PCI
Organizations often handle multiple categories of sensitive data, each governed by different regulations and security requirements.
Most organizations process more than one of these data types simultaneously, making accurate and automated redaction essential for maintaining compliance and protecting sensitive information across different workflows.
How We Evaluated These PII Redaction Tools
Every organization has different requirements when choosing a PII redaction solution. A healthcare provider may prioritize HIPAA compliance and deployment flexibility, while a software company may focus on API integrations and AI workflows. Rather than ranking tools based on a single capability, we evaluated each platform across the criteria enterprise buyers and developers commonly consider.
Our evaluation considered:
- Detection capabilities: The range of PII and sensitive data types each platform is designed to identify and redact.
- Context awareness: Whether the solution relies on pattern matching or uses AI to understand surrounding context and intent.
- Supported data types: Coverage across text, documents, PDFs, images, audio, transcripts, and AI prompts.
- Developer experience: API availability, SDK support, documentation quality, and ease of integration.
- Deployment flexibility: Availability of cloud, API, self-hosted, on-premises, or containerized deployment options.
- Enterprise security: Encryption, audit logs, role-based access controls, governance capabilities, and data residency options.
- Compliance support: Support for regulatory requirements such as GDPR, HIPAA, SOC 2, ISO 27001, and other applicable standards.
- Performance: Support for real-time, streaming, or batch processing workloads where applicable.
- Pricing model: How each vendor structures licensing and usage.
- Ease of implementation: The effort required to integrate the platform into existing applications and enterprise workflows.
- Best-fit use cases: The types of organizations and workloads each platform is best suited to support.
The following comparison highlights where each platform excels, its limitations, and the types of organizations it is best suited for. Where vendors publish performance or accuracy metrics, they are identified as vendor-reported unless independently validated.
PII Redaction Tools Comparison at a Glance
1. Wald
Wald offers a state-of-the-art Developer API that goes beyond PII removal. It aims to safeguard content based on context to ensure AI can use it.
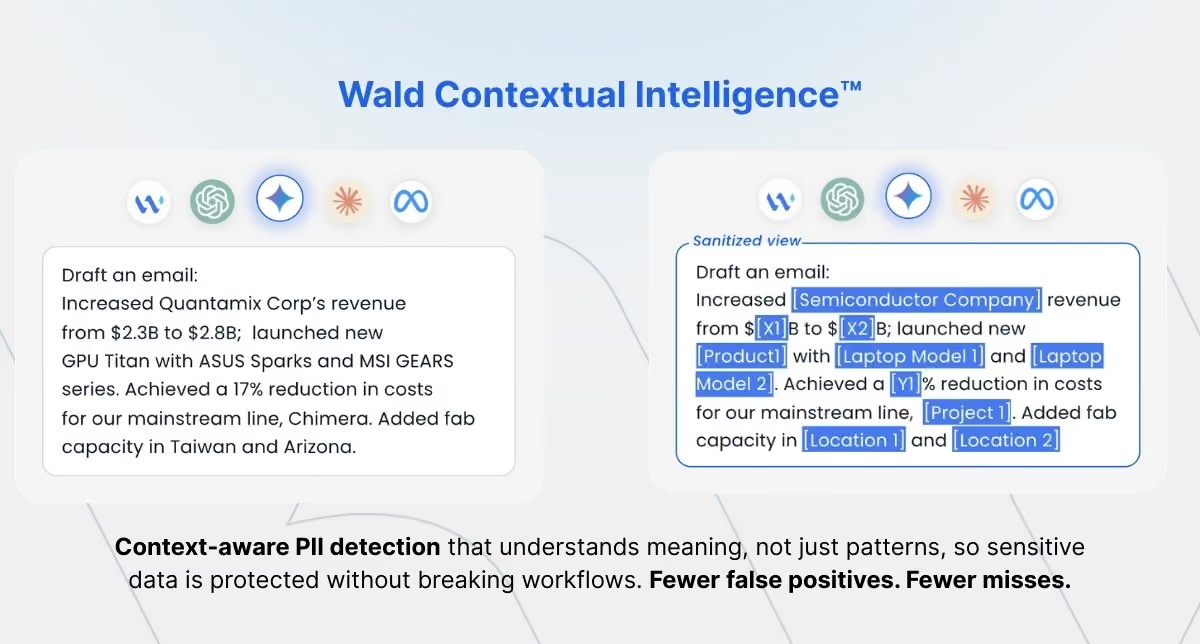
Unlike traditional PII redaction tools that focus on documents or datasets, Wald is purpose-built for securing enterprise AI interactions. It sits between users and large language models (LLMs) such as ChatGPT, Claude, Gemini, and Grok, automatically detecting, redacting, and later restoring sensitive information so employees can safely use AI without exposing confidential business data.
Best For
Organizations deploying enterprise AI assistants, or custom knowledge agents that require contextual PII redaction, governance, and secure AI adoption.
Detection Capabilities
Wald is designed to detect and redact multiple categories of sensitive information before it reaches an LLM, including 40+ entities such as personally identifiable information (PII), financial information, customer records, employee information, and proprietary business data. Rather than focusing solely on predefined identifiers, it aims to protect sensitive enterprise content across AI interactions.
Context Awareness
One of Wald's primary differentiators is its context-aware approach to redaction. Instead of relying solely on regex or pattern matching, it analyzes conversational context to determine what information should be protected while preserving the surrounding meaning. This helps maintain response quality by restoring sensitive values after the AI generates a response.
Supported Data Types
Wald primarily secures AI interactions involving:
- AI prompts and responses
- Chat conversations
- Business documents and text
- Source code
- Customer and employee data
- Proprietary enterprise information
Unlike document-focused platforms, Wald is designed around AI workflows rather than PDF or image redaction.
Deployment
- Managed SaaS platform
- Developer API
- Cloud deployment
Enterprise Security
- End-to-end encryption
- Role-based access control (RBAC)
- Audit logs
- AI governance policies
- Usage analytics
Compliance
SOC 2 Type II certified. Designed to help organizations support privacy requirements including GDPR, HIPAA, and CCPA by preventing sensitive information from being exposed to third-party AI models.
Developer Experience
Wald provides a Developer API for integrating contextual redaction into AI applications and enterprise workflows. It is designed to sit between users and foundation models, allowing organizations to introduce security controls without changing existing AI applications.
Pricing
Strengths
- Purpose-built for enterprise AI security
- Context-aware prompt sanitization
- Preserves conversational context after redaction
- AI governance capabilities beyond traditional document redaction
- Supports multiple enterprise LLMs
Limitations
- Primarily focused on AI interactions rather than document-centric workflows
- Native OCR and speech processing are not primary use cases
Use Case
A financial services organization can allow employees to safely use ChatGPT, Claude, or Gemini by automatically redacting customer information, account numbers, and proprietary business data before prompts reach the model, while restoring the original values in the final response.
2. Limina AI (formerly Private AI)
Limina AI (formerly Private AI) is an AI-powered de-identification platform that automatically detects, removes, or replaces sensitive information across unstructured data. Unlike solutions built primarily for AI assistants or document workflows, Limina is designed as a privacy layer for enterprise data pipelines, enabling organizations to anonymize text, documents, images, and audio while keeping data within their own infrastructure.
Best For
Organizations prioritizing data privacy, regulatory compliance, and flexible deployment across multilingual environments.
Detection Capabilities
Limina is designed to identify and redact over 50 categories of sensitive information, including personally identifiable information (PII), protected health information (PHI), financial data, government-issued identifiers, and other sensitive entities across structured and unstructured content. Organizations can also configure custom policies to determine which entities should be redacted, replaced, or preserved.
Context Awareness
Unlike traditional regex-based approaches, Limina uses machine learning models to understand context before identifying sensitive information. It can replace detected entities with contextually appropriate synthetic values, helping preserve readability while protecting privacy.
Supported Data Types
Limina supports a broad range of unstructured enterprise data, including:
- Plain text
- PDF and Word documents
- Images
- Audio and transcripts
- Emails
- Customer conversations
- AI and analytics pipelines
Its OCR and speech processing capabilities allow organizations to redact sensitive information before downstream processing or model training.
Deployment
Limina is designed for organizations that require complete control over sensitive data and supports:
- Self-hosted deployment
- On-premises deployment
- Virtual Private Cloud (VPC)
- Docker containers
- Kubernetes environments
Because processing occurs within the customer's infrastructure, sensitive data does not leave the organization's environment.
Enterprise Security & Compliance
- Customer-controlled data processing
- Regional data residency through customer-managed infrastructure
- Configurable retention policies
- Supports organizations subject to GDPR, HIPAA, CPRA, APPI, and other privacy regulations
- Business Associate Agreements (BAAs) available for HIPAA use cases
Developer Experience
Limina is built for developers and data engineering teams. It provides a containerized API, developer documentation, SDKs, and integrations for enterprise data pipelines, allowing organizations to embed automated de-identification into AI, analytics, and machine learning workflows.
Pricing
Enterprise pricing is available through their website.
Strengths
- Supports over 50 PII entity types across approximately 50 languages
- Broad support for text, documents, images, audio, and transcripts
- Fully self-hosted deployment for maximum data control
- Strong compliance posture for regulated industries
- Context-aware replacement helps preserve document usability after redaction
Limitations
- No fully managed SaaS offering
- Enterprise-focused deployment requires containerized infrastructure
Use Case
A multinational financial institution can automatically anonymize emails, customer communications, documents, and transcripts before they are ingested into analytics platforms or AI applications, while ensuring sensitive information never leaves its own cloud environment.
3. Redactable
Redactable is an AI-powered document redaction platform built for organizations that need to quickly and securely remove sensitive information from PDFs and scanned documents. Unlike platforms focused on AI workflows or APIs, Redactable is designed for legal, compliance, government, and operations teams that require an intuitive, no-code solution for document review and redaction.
Best For
Legal, compliance, government, and operations teams that regularly redact PDF documents, scanned files, and other document-based records.
Detection Capabilities
Redactable automatically detects and redacts common categories of sensitive information found in documents, including personally identifiable information (PII), financial information, names, addresses, Social Security numbers, credit card numbers, and other confidential data. It also permanently removes hidden metadata to reduce the risk of inadvertent disclosure.
Context Awareness
Redactable combines OCR with AI-assisted detection to identify sensitive information within documents. While it automates much of the redaction process, its primary focus is document-based pattern and entity recognition rather than contextual understanding across conversational or AI-generated content. Human review remains an important part of validating redactions before documents are finalized.
Supported Data Types
Redactable supports a variety of document formats, including:
- PDF documents
- Scanned PDFs
- Images
- Microsoft Office documents
- Legal contracts
- Medical records
- Government records
Its built-in OCR enables sensitive information to be detected even within scanned or image-based documents.
Deployment
Redactable is primarily available as a cloud-based SaaS platform.
Enterprise Security & Compliance
- SOC 2 Type II certified
- HIPAA compliant
- AES-256 encryption at rest
- TLS encryption in transit
- Audit trails for document review and redaction
- Team collaboration and user management capabilities
Developer Experience
Redactable is designed primarily as a no-code application for business users rather than a developer platform.
Pricing
- Free plan (up to three documents)
- Pay-as-you-go pricing
- Subscription plans for individual users and teams
- Enterprise pricing available upon request
Strengths
- Purpose-built for document redaction
- Excellent OCR support for scanned documents
- Permanent metadata removal
- Built-in audit trails for compliance workflows
- Easy-to-use interface requiring little technical expertise
Limitations
- Focused primarily on document workflows rather than AI or conversational data
- No developer API
- Limited self-hosted deployment options
- Less suitable for real-time or streaming redaction use cases
Use Case
A legal team preparing documents for litigation or responding to a Freedom of Information Act (FOIA) request can automatically detect and permanently redact sensitive information from hundreds of PDFs while maintaining an auditable record of every redaction applied.
4. AssemblyAI
AssemblyAI is a speech AI platform that combines industry-leading speech recognition with built-in PII redaction capabilities. Unlike traditional document redaction tools, it is designed for developers building voice applications, enabling organizations to automatically detect and redact sensitive information from audio, video, and transcripts in real time or batch workflows.
Best For
Developers and organizations building speech-to-text, contact center, voice AI, and conversational AI applications that require automated PII redaction.
Detection Capabilities
AssemblyAI automatically detects and redacts common categories of personally identifiable information (PII) from transcripts and audio. Its Guardrails capabilities support the removal or masking of names, phone numbers, addresses, credit card numbers, government-issued identifiers, and other sensitive entities. Organizations can also configure custom PII redaction policies based on their requirements.
Context Awareness
AssemblyAI combines automatic speech recognition (ASR) with AI-powered entity recognition to identify sensitive information within spoken conversations. While its primary strength lies in speech processing, it also supports contextual entity detection across transcripts rather than relying solely on predefined pattern matching. AssemblyAI reports high accuracy for entity recognition in supported benchmarks, although independent cross-vendor comparisons remain limited.
Supported Data Types
AssemblyAI supports a variety of speech and conversational data, including:
- Audio files
- Video files
- Live streaming audio
- Speech transcripts
- Customer support conversations
- Contact center recordings
- Voice assistant interactions
Its APIs support both real-time streaming and asynchronous batch processing workflows.
Deployment
AssemblyAI is available as a cloud-based API and also offers self-hosted deployment options for organizations with strict security or regulatory requirements.
Enterprise Security & Compliance
- SOC 2 Type II certified
- ISO 27001 certified
- PCI DSS compliant
- AES-256 encryption at rest
- TLS 1.3 encryption in transit
- US and EU data residency options
Developer Experience
AssemblyAI is built for developers and provides comprehensive REST APIs, official SDKs, detailed documentation, code samples, and interactive testing tools. It supports multiple programming languages and integrates easily into existing speech and AI workflows.
Pricing
AssemblyAI follows a usage-based pricing model, charging based on the number of audio minutes processed. Enterprise plans and specialized capabilities, such as Medical Speech Recognition, are available separately.
Strengths
- Purpose-built for speech and voice AI applications
- High-quality speech recognition with integrated PII redaction
- Supports both streaming and batch processing
- Strong developer experience with mature APIs and SDKs
- Extensive enterprise security and compliance certifications
Limitations
- Primarily focused on audio and speech workflows rather than document or enterprise AI governance
- Requires audio transcription before sensitive information can be redacted
- Usage-based pricing may become costly for high-volume speech processing workloads
Use Case
A contact center can automatically transcribe customer calls, redact sensitive information such as payment details and personal identifiers, and store compliant transcripts for quality assurance, analytics, and agent training without exposing regulated data.
Enterprise Buying Considerations for PII Redaction Tools
Now that we understand the solutions available and their apt use cases, an enterprise must consider how well a solution integrates with their current stack. What would introducing a new PII redaction tool mean for your existing security, compliance, and AI infrastructure? Before making your pick, consider the following capabilities:The table below summarizes some of the key capabilities enterprise buyers should evaluate before selecting a PII redaction platform.
While every organization has different priorities, enterprise buyers should avoid evaluating solutions based solely on the number of supported entity types or languages. Context-aware detection, deployment flexibility, governance capabilities, and ease of integration often have a greater impact on long-term adoption than feature checklists alone.
Enterprise Feature Comparison
Why these capabilities matter
No single platform excels across every category. Organizations deploying enterprise AI assistants may prioritize contextual redaction and AI governance, while healthcare providers may require self-hosted deployments and strict data residency controls. Legal teams often benefit from document-first workflows with OCR and audit trails, whereas contact centers typically require real-time speech transcription and audio redaction.
Understanding these trade-offs helps narrow the list of potential solutions before comparing individual features or pricing.
Regex vs AI-Based PII Redaction
For years, organizations relied on regular expressions (regex) to identify and redact sensitive information such as email addresses, phone numbers, credit card numbers, and Social Security numbers. While regex remains effective for structured data that follows predictable patterns, modern AI applications increasingly process unstructured conversations, documents, and prompts where sensitivity depends on context rather than format.
This shift has driven the adoption of AI-powered PII redaction, which combines machine learning and natural language processing (NLP) to identify sensitive information based on both the data itself and the surrounding context.
Many enterprise platforms combine regex and AI models, using pattern matching to identify structured identifiers while applying contextual AI models to detect names, organizations, healthcare information, proprietary business data, and other sensitive content that cannot be reliably identified using rules alone.
Since AI models frequently process long-form conversations, contextual detection for documents, source code, and business knowledge where the sensitivity of information depends on how it is used rather than how it is formatted.
LLM-Based PII Redaction
Traditional PII redaction was primarily designed for static documents and databases. Today, organizations are increasingly sharing sensitive information with large language models (LLMs) through AI assistants, copilots, chatbots, and custom AI applications, creating new privacy and compliance challenges.
LLM-based PII redaction addresses this by identifying and removing sensitive information before prompts are sent to an AI model. Depending on the platform, the original values may be restored after the model generates a response, allowing users to preserve context without exposing confidential information to third-party AI services.
Common LLM redaction workflows include:
- Redacting customer information before prompts are sent to ChatGPT, Claude, Gemini, or other LLMs.
- Protecting proprietary business information, source code, financial data, and internal documents during AI-assisted workflows.
- Applying organization-wide security policies before employees interact with enterprise AI assistants.
- Preventing sensitive information from being retained by downstream AI applications.
For organizations deploying AI at scale, LLM-based redaction has become an important component of AI governance. It enables employees to use AI tools productively while reducing the risk of exposing confidential information or violating internal security policies.
Why Context Matters
A person's name, company name, or product identifier is not always sensitive on its own. Whether information should be redacted often depends on the surrounding context.
For example:
These examples illustrate why context-aware models are becoming increasingly important for enterprise AI workflows. Rather than relying solely on predefined patterns, modern PII redaction platforms analyze surrounding words and sentence structure to determine whether information is sensitive, reducing unnecessary redactions while helping prevent confidential information from being missed.
Batch vs Streaming PII Redaction
Organizations process sensitive information in different ways. Some need to redact millions of existing documents before migrating to a new system, while others must protect sensitive information in real time as users interact with AI assistants or customer service platforms.
Modern PII redaction platforms typically support one or both of these approaches.
Batch redaction is commonly used when organizations need to sanitize historical documents before analytics, AI training, or cloud migration. Streaming redaction, on the other hand, protects sensitive information before it reaches downstream applications, making it particularly valuable for generative AI, customer support, and voice AI use cases.
Why Redaction APIs Matter
For many organizations, PII redaction is no longer a standalone application. Instead, it is embedded directly into business applications, AI workflows, and enterprise data pipelines through APIs.
API-first redaction enables developers to automatically detect and remove sensitive information before data is stored, shared, or processed by downstream systems.
Common use cases include:
- Protecting AI prompts before they are sent to large language models (LLMs).
- Redacting customer information before storing chat conversations.
- Sanitizing documents before indexing them for retrieval-augmented generation (RAG).
- Removing sensitive information before data is ingested into analytics or machine learning pipelines.
- Protecting customer conversations in contact center applications.
When evaluating a PII redaction API, organizations should consider:
- Documentation quality
- SDK availability
- Authentication and security controls
- Latency and throughput
- Supported programming languages
- Integration with existing AI and data workflows
While developer APIs are essential for engineering teams building custom applications, organizations with primarily document-based workflows may prefer a no-code platform with built-in review and collaboration capabilities.
OCR Challenges in PII Redaction
Sensitive information isn't always stored as searchable text. Many organizations work with scanned contracts, handwritten forms, invoices, medical records, passports, and other image-based documents that first need to be converted into machine-readable text.
This is where Optical Character Recognition (OCR) becomes an essential part of the redaction process.
Common OCR challenges include:
- Low-quality scans
- Handwritten text
- Skewed or rotated documents
- Multi-column layouts
- Tables and forms
- Poor image resolution
- Mixed languages
Errors introduced during OCR can affect downstream PII detection, causing sensitive information to be missed or incorrectly identified. As a result, organizations processing scanned documents should evaluate both OCR quality and redaction accuracy rather than treating them as separate capabilities.
For document-heavy workflows such as legal discovery, healthcare records, and government archives, robust OCR can significantly improve the effectiveness of automated PII redaction while reducing the amount of manual review required.
Common False Positives and False Negatives
No automated PII redaction solution is perfect. Organizations should evaluate not only how much sensitive information a platform detects, but also how often it incorrectly redacts non-sensitive content or misses information that should have been protected.
A false positive occurs when information is unnecessarily redacted.
Example:
"Apple announced its latest quarterly earnings."
In this case, Apple refers to a public company and generally shouldn't be redacted.
A false negative occurs when sensitive information is not redacted.
Example:
"Sarah Johnson's employee ID is EMP-47281."
If the employee's name or identifier is missed, the document may still expose sensitive information despite being processed.
Context-aware AI models help reduce both types of errors by analyzing how information is used within a sentence rather than relying solely on predefined patterns. However, organizations handling highly regulated data should still incorporate human review for high-risk workflows, particularly when processing legal documents, healthcare records, or financial information.
Other PII Redaction Tools Worth Considering
The four tools covered above represent different approaches to PII redaction, but they're not the only options available. Depending on your use case, you may also want to evaluate cloud-native services, data security platforms, and enterprise governance solutions.
These platforms address different aspects of data protection. Cloud providers such as Azure, Google Cloud, and AWS offer native PII detection services that integrate with their respective ecosystems, while platforms like BigID and Securiti focus on enterprise data discovery and governance. Microsoft Presidio is a popular choice for organizations building custom redaction pipelines, whereas document management vendors such as OpenText provide broader information governance capabilities alongside redaction features.
When selecting a solution, organizations should evaluate whether they need a specialized redaction platform, an AI security layer, or a broader data governance solution that includes PII detection as one component of a larger privacy program.
Conclusion
Choosing the right PII redaction tool depends on the type of data your organization processes, the applications you need to protect, and your security and compliance requirements.
If your primary focus is securing enterprise AI interactions and preventing sensitive information from reaching large language models, platforms such as Wald provide contextual redaction designed specifically for AI workflows. Organizations looking to anonymize large volumes of enterprise data across documents, images, and analytics pipelines may prefer Limina AI, while legal and compliance teams working primarily with documents may benefit from Redactable's document-first approach. For organizations processing customer conversations, contact center recordings, and voice applications, AssemblyAI offers built-in speech recognition and PII redaction capabilities.
The best solution is ultimately the one that fits your organization's workflows, regulatory obligations, and long-term AI strategy.
Frequently Asked Questions
What is PII redaction?
PII redaction is the process of identifying and removing, masking, or replacing personally identifiable information (PII) before it is stored, shared, or processed. Common examples include names, email addresses, phone numbers, government-issued identification numbers, payment information, and customer identifiers.
How does AI-powered PII detection work?
AI-powered PII detection combines machine learning and natural language processing (NLP) to identify sensitive information based on both patterns and context. Unlike traditional regex-based detection, AI models can recognize sensitive information even when it doesn't follow a predefined format.
Can ChatGPT automatically redact PII?
No. ChatGPT is not designed to automatically detect and remove sensitive information before processing prompts. Organizations handling confidential information often use AI security or PII redaction platforms to sanitize prompts before they are sent to large language models.
What is contextual redaction?
Contextual redaction uses AI to understand how information is used within a sentence before deciding whether it should be removed. This helps reduce unnecessary redactions while improving detection of sensitive information that cannot be identified through pattern matching alone.
Which PII redaction tools support HIPAA?
Several enterprise PII redaction platforms offer capabilities designed to support organizations operating under HIPAA requirements. Depending on the deployment model and use case, examples include Limina AI, AssemblyAI, Redactable, and AI security platforms such as Wald. Organizations should evaluate each vendor's security controls, deployment options, and contractual commitments before selecting a solution.