Vinay is the CEO and co-founder of Wald.ai, a pioneer in data security for Gen AI. Vinay was CPTO at Kiavi, a leading Fintech in the mortgage lending space. As Chief Digital Officer at JLL, a Fortune 150 company, he led and scaled a global product development organization. Prior to JLL, he spent over a decade at Google leading product teams across Google Maps and Enterprise. He has a strong background in internet security after leading products at companies like CheckPoint Software and Webroot.
Why Traditional DLP Cannot See What Gets Typed Into AI Tools
Traditional DLP Was Built for Discrete File Transfers
Traditional data loss prevention systems operate on a single assumption: sensitive data moves as identifiable objects across monitored boundaries. Email attachments trigger scans. USB transfers generate alerts. File uploads to cloud storage pass through gateways where pattern matching runs against the payload. The architecture worked because data exfiltration followed a predictable structure.
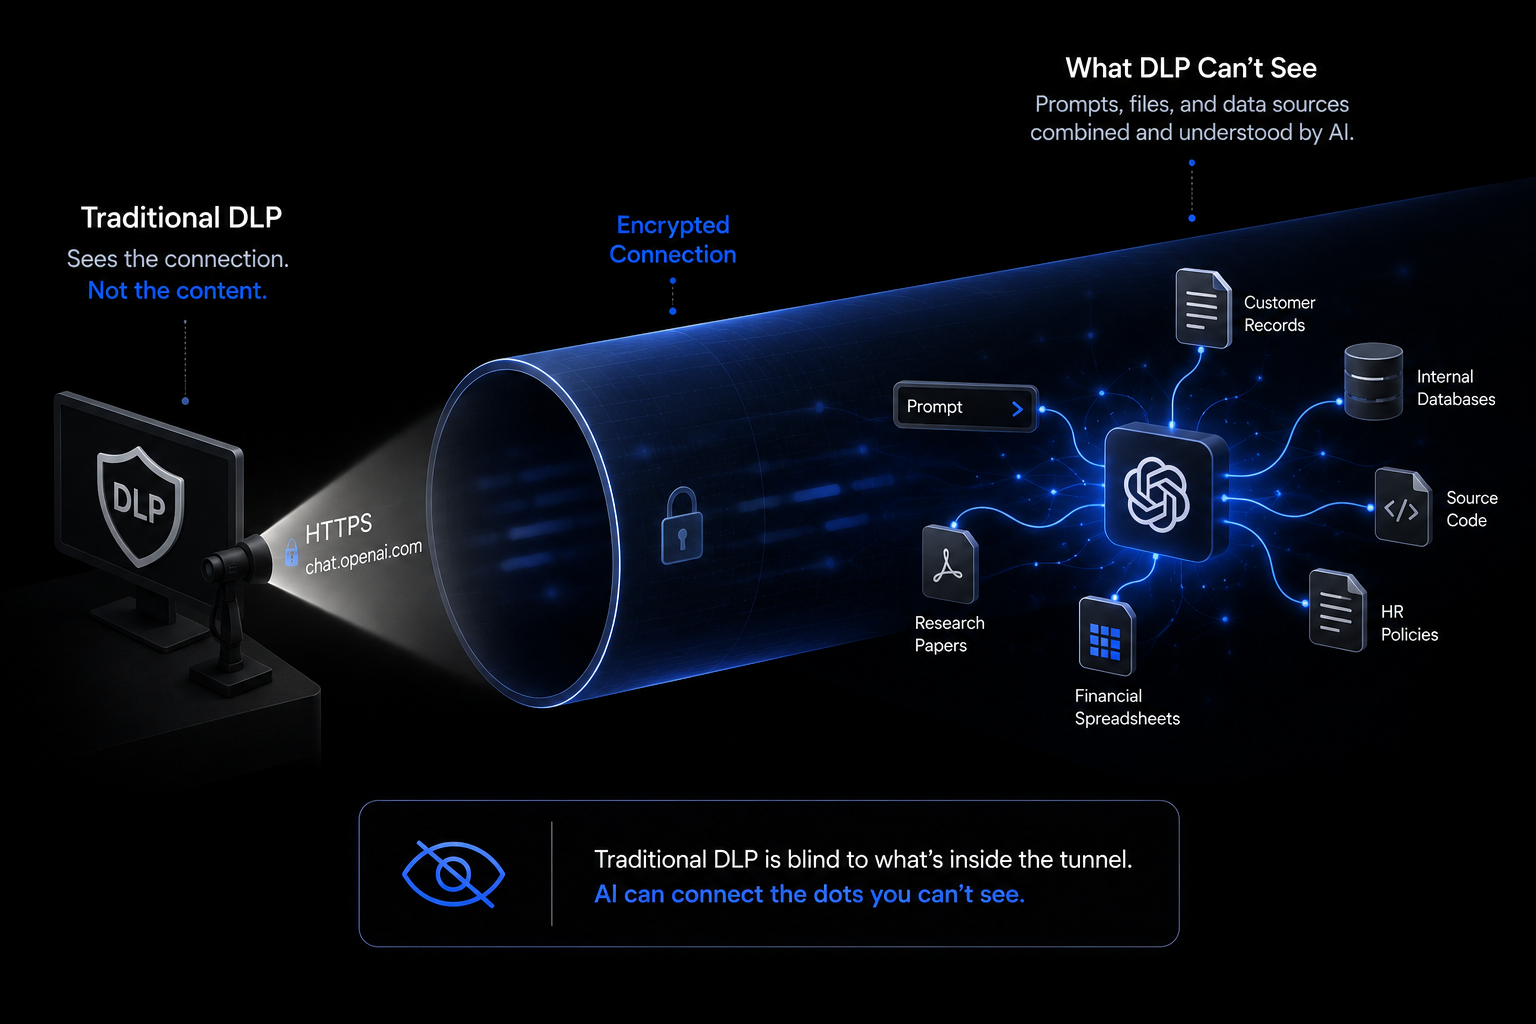
Generative AI tools break that structure entirely. When an employee copies a block of text from a customer database and pastes it into ChatGPT, no file leaves the endpoint. No attachment crosses the email gateway. The DLP agent watching the device sees an HTTPS connection to a known domain, but the prompt content travels encrypted inside the API request body. Without visibility into that text payload, legacy endpoint and network DLP systems have no mechanism to classify what just left the organization.
Pattern Matching Misses Natural Language Prompts
Regex-based pattern matching was designed to catch structured data: credit card numbers, Social Security Numbers, specific file types. Conversational prompts do not follow those patterns. A user can type "Summarize the Q3 pipeline for our top healthcare accounts" without including a single element that would trigger a traditional DLP rule. That prompt still surfaces deal values, client names, and contract terms in the AI's response.
The Samsung incident makes this visible. Engineers pasted proprietary semiconductor source code into ChatGPT across multiple sessions before the company identified what had happened. The code contained no SSN patterns. No card numbers. Legacy DLP watched the traffic and flagged nothing, because the content was unstructured technical IP that fell outside every predefined rule.
Browser-Only Tools Miss Desktop AI Applications
Browser extensions intercept prompts typed into web-based AI tools. They cannot see desktop applications. ChatGPT Desktop, Claude Desktop, Cursor, and other native AI clients access local filesystems, read clipboard data, and execute actions at the OS level without generating the network events that browser-based DLP relies on. A developer can drag a confidential PDF directly into Claude Desktop, and a browser extension has zero visibility into that interaction.
The coverage gap is not a configuration problem. It is a structural one.
Two Ways the Market Is Solving This, and Where Each One Falls Short
Behavioral and Endpoint Surveillance Approach
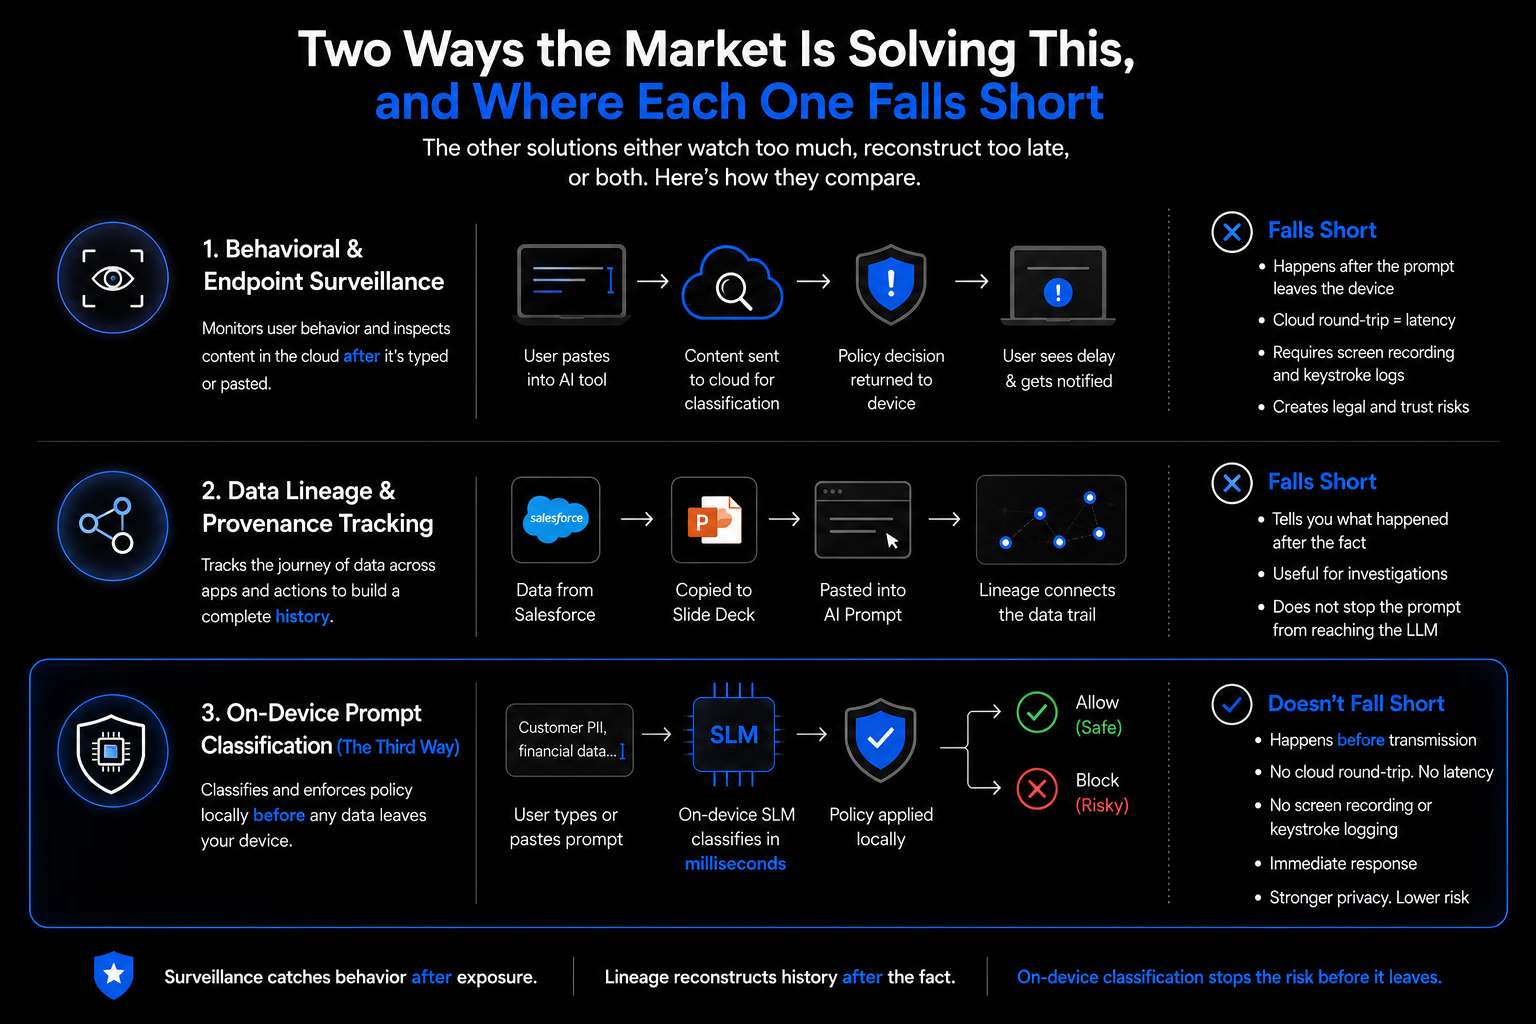
The first wave of AI DLP extends traditional endpoint controls into browser sessions. Platforms like Microsoft Purview monitor user behavior through Indicators of Behavior (IoBs), adjusting enforcement based on calculated risk scores. When a user attempts to paste content into a browser window, the system captures it, sends it to cloud-based classification, and returns a policy decision to the local device.
The problem is sequencing. Classification happens after the prompt leaves the device. Cloud analysis introduces latency, and users sit through policy-evaluation notifications while the system processes content. That alone creates friction.
The deeper issue is what these systems collect to make it work. Some implementations require screen recordings and keystroke logs to reconstruct data activity. For mid-market teams, that creates legal exposure and employee trust problems that are harder to manage than the original data risk.
Data Lineage and Provenance Tracking Approach
Data lineage tools take a different approach. Instead of monitoring behavior, they track where data originates and how it moves. If an employee copies text from Salesforce into a slide deck and then pastes it into an AI prompt, lineage tracking connects those steps into a single data history. The system builds that context by monitoring clipboard actions, browser behavior, and application usage in real time.
The limitation is directional. Lineage tracking tells you what happened after the fact. It is useful for investigations and forensic reviews, but it does not stop anything. By the time a lineage system flags a policy violation, the prompt has already reached the LLM.
The Third Way: On-Device Prompt Classification
On-device classification moves the enforcement point to before transmission. A small language model (SLM) runs directly on the endpoint, reading prompt content locally before any API request leaves the device. Classification completes in milliseconds. The policy decision executes before the data moves.
No cloud round-trip. No screen recording. No keystroke logging. The agent reads the prompt, classifies the content, applies the relevant policy, and either allows or blocks the request. The user sees an immediate response.
That is the gap the first two approaches do not close. Surveillance catches behavior after exposure. Lineage reconstructs history after the fact. On-device classification stops the risk before it leaves.
How Wald's Desktop DLP Agent Classifies Prompts Before They Leave the Device
On-Device SLM Classification
Wald runs a small language model directly on the endpoint. Every prompt gets read before it reaches an external AI service. Classification completes locally in under a second, with no visible delay for the user.
The distinction from traditional pattern matching is significant. The model analyzes semantic meaning, not keyword patterns. It can differentiate between a developer pasting debugging code and an employee uploading customer payment records, even when neither contains a flagged term. That level of contextual understanding is what regex-based rules cannot replicate.
Small language models operate with fewer than 10 billion parameters, which makes them efficient in resource-constrained environments. Classification runs on standard employee devices without GPU acceleration or cloud connectivity. Sensitive prompt content never leaves the device unencrypted for analysis.
Why the Agent Architecture Matters
Browser extensions intercept prompts entered into web-based AI tools. Desktop applications are outside their reach. Wald's desktop agent operates at the OS level, capturing clipboard actions, form submissions, and file uploads across browsers, native AI clients, and any application that connects to an external AI service.
This covers ChatGPT Desktop, Claude Desktop, Cursor, and other native clients that browser-only tools miss entirely.
Wald enforces policy through four distinct actions:
Allow: The prompt passes without restriction beyond standard audit logging
Monitor: The activity generates a security team event without interrupting the user
Warn: The user receives an inline notification explaining the policy concern and can choose to proceed or revise
Block: Transmission is prevented and the attempt is logged
The granularity here matters. Organizations that go straight to hard blocks tend to push employees toward personal accounts and unsanctioned tools. Starting in monitor mode establishes a usage baseline. Warnings coach users at the point of action. Blocks get applied selectively, where the risk actually warrants it.
This supports a progressive rollout rather than a disruptive one.
Platform Coverage
The agent monitors ChatGPT, Claude, Gemini, and Microsoft Copilot across both browser and desktop interfaces. Coverage applies regardless of which surface the employee is working from.
What to Look for in a Generative AI DLP Solution for a Regulated Mid-Market Team
Choosing an AI DLP solution is not just a feature comparison exercise. For regulated mid-market teams, the gap between what a solution claims to do and what it actually enforces in practice determines whether data stays protected or not.
These are the criteria that matter.
Real-Time Inline Enforcement
The enforcement point is everything. Solutions that route prompts through cloud-based classification or analyze content after transmission introduce a window where sensitive data has already left the device. That window is where exposure happens.
Inspection must occur at the endpoint, before the API call executes. Anything else is detection, not prevention. For regulated teams, detection after the fact does not satisfy compliance requirements or reduce actual risk.
Desktop-Native AI App Coverage
Browser extensions cover web-based AI tools. They cannot see what happens inside desktop applications.
ChatGPT Desktop, Claude Desktop, Cursor, and similar native clients operate at the OS level. They bypass browser-based controls entirely. An employee can paste a confidential document directly into a desktop AI client, and a browser extension will not register the event.
Endpoint agents that intercept at the system level cover both surfaces. Without that OS-level coverage, there are blind spots that users will find, whether intentionally or not.
Compliance Framework Support
Regulated teams cannot build policy from scratch for every data type. Solutions should include pre-built templates aligned to HIPAA, GDPR, PCI-DSS, and CCPA requirements.
Detection needs to identify PHI, PII, cardholder data, and other regulated content types without requiring manual rule creation for each scenario. Audit logs must document what was detected, which policy applied, and what action the system took. Regulators expect that level of traceability. Solutions that cannot produce it create liability rather than reducing it.
Deployment for Lean IT Teams
Most mid-market security teams do not have a dedicated DLP administrator. They cannot absorb a multi-month deployment or ongoing tuning cycles that require specialist knowledge.
Solutions should be operational in days. Agents should run with low performance overhead that does not generate help desk tickets. Minimal configuration on the front end, and minimal maintenance after.
If deployment complexity becomes its own project, the solution is adding operational burden rather than reducing risk.
Policy Granularity for Coaching and Warnings
Hard blocks create friction. Friction drives users toward personal accounts and unsanctioned tools. That trade-off consistently produces worse outcomes than the risk the block was meant to prevent.
Policy engines that support monitor, warn, and block modes allow teams to roll out controls progressively. Users receive coaching at the point of action, which builds awareness without interrupting workflow. Over time, that approach changes behavior more effectively than enforcement alone.
Static block-or-allow is not a policy strategy. It is the absence of one.
FAQs
What is Generative AI DLP?
Generative AI DLP is a security framework that inspects, classifies, and governs sensitive data as it moves into and out of AI systems through prompts, uploads, and model responses. Traditional DLP monitors email attachments and file transfers. Generative AI DLP watches the prompt box — the conversational interface where employees interact directly with external AI platforms.
Is Generative AI DLP the Same as Blocking ChatGPT or Claude?
No. Blocking AI tools entirely pushes employees toward personal accounts and unsanctioned services. That is how shadow AI expands. Generative AI DLP allows approved interactions to proceed while blocking or redacting sensitive content in real time — maintaining productivity without leaving data exposure unaddressed.
Does Generative AI DLP Work on Desktop Apps?
Endpoint-based solutions monitor desktop AI applications including ChatGPT Desktop, Claude Desktop, and similar native clients that browser extensions cannot reach. Coverage requires OS-level interception. Without it, activity across desktop apps and any application accessing external AI services falls outside visibility entirely.
Does Generative AI DLP Require Screen Recording or Keystroke Logging?
Not necessarily. Some legacy approaches reconstruct data activity through screen recordings and keystroke logs. Modern on-device classification analyzes prompt content directly, without the surveillance overhead that creates employee trust issues and raises legal questions.
What Compliance Frameworks Does Generative AI DLP Need to Support?
Regulated teams require coverage for HIPAA, GDPR, PCI DSS, and CCPA. Detection needs to identify PHI, PII, cardholder data, and other regulated content types. Audit logs must document what was detected, which policy applied, and what action was taken — not just for internal review, but to satisfy regulatory expectations.
AI has become part of daily work. Employees use it to draft emails, write code, analyze documents, and speed up routine tasks. Productivity is improving, but something else is happening quietly in the background. Sensitive data is slipping into systems that were never built to protect it.
This is not hypothetical. It is real, it is happening today, and it is dangerous. Every time an employee pastes a customer record, a financial detail, or even a snippet of source code into an AI tool, the company’s risk exposure grows. The intent may be harmless, but the outcome can be severe.
Why This Matters More Than Leaders Realize
Enterprises carry large volumes of personally identifiable information (PII) and regulated data. Compliance with GDPR, HIPAA, PCI-DSS, SOC 2, or CCPA is not optional. Regulators do not accept “we did not know.” Boards cannot excuse reputational damage. Customers will not forgive carelessness.
The truth is that most AI tools were not designed for compliance. They were created to generate answers, to accelerate work, and to feel intuitive. They are powerful, but they are not secure by default. When employees put sensitive information into them, the company inherits risks it cannot see and cannot control.
The New Reality of Work
Here is the reality. Employees will use AI. They will use it whether policies allow it or not. It is too fast, too convenient, and too effective to ignore. Writing memos or trying to ban AI is not a strategy. It is wishful thinking.
The question for leadership is not “will employees use AI?” They already do. The real question is “how do we see and control what happens when they use it?”
Sensitive data does not always look like a credit card number or a Social Security ID. Sometimes it is the structure of a contract, a client proposal, or an internal strategy document. Context makes it sensitive. Detecting that requires more than pattern matching. It requires intelligence that understands meaning.
How Wald.ai Solves This Challenge
At Wald.ai, we built our DLP platform for exactly this challenge. Traditional systems look for fixed identifiers. Ours looks at context and intent. That difference changes how enterprises stay safe.
When an employee uses ChatGPT, Claude, or Gemini, Wald.ai works in real time. It sees what information is leaving. It recognizes sensitivity even when obvious markers are missing. It gives leaders visibility without slowing employees down. Compliance is protected, and productivity continues. Security becomes a driver of trust, not an obstacle to progress.
A Call to Leadership
Keeping sensitive data safe in an AI driven workplace is not tomorrow’s challenge. It is today’s responsibility. Leaders who wait will explain breaches. Leaders who act will protect customers, employees, and investors.
The steps are clear. Accept that employees will use AI. Recognize that sensitive data will reach those tools unless controls are in place. Invest in solutions that understand both context and intent. Treat security as a culture, not just a checkbox.
The companies that move first will not only avoid fines and headlines. They will build trust, move faster, and create a foundation for innovation. At Wald.ai, we believe that is the only sustainable way forward.
Use ChatGPT and other AI models with confidence. Wald keeps sensitive data out of the model while preserving intent and context in every conversation.
Try it free and experience private AI, the way it should be.
ChatGPT is powerful, no doubt. But for businesses that live and breathe sensitive information, the question is less about capability and more about safety. AI is reshaping entire industries—PwC says it could add $15.7 trillion to the global economy by 2030. That’s massive. But growth this big always carries risk.
We’ve already seen warning signs. Italy’s data protection authority flagged privacy issues. Samsung had employees accidentally leak confidential data. Children’s Hospital Colorado paid a $548,265 HIPAA fine after breaches. These aren’t small stories—they’re flashing red lights for any organization that has to comply with GDPR, HIPAA, or similar regulations.
Here’s the thing: your choice of ChatGPT deployment—public or private—directly shapes your risk profile. Let’s break it down.
Data Flow and Privacy: Where Does Your ChatGPT Data Go?
The single biggest question businesses should ask: where does my data actually go?
Public ChatGPT: Everything runs through OpenAI
When you use the public app, every prompt, every file, every response goes to OpenAI servers. Their policy admits: “we may use content submitted to ChatGPT to improve model performance.” That means your data might travel across systems in the US and elsewhere. And yes, a “limited number of OpenAI personnel” may access it. If you’re handling sensitive data, that’s a serious exposure.
Private ChatGPT: You own the flow
Private deployments—on-prem or within a Virtual Private Cloud (VPC)—keep data inside your walls. Nothing leaves unless you allow it. You control the configuration, storage, and policies. For industries that simply cannot risk leaks, this control is critical.
Why data sanitisation matters
Regardless of where you run ChatGPT, you need guardrails:
AES-256 encryption for data in transit and at rest
Redaction or anonymization of sensitive fields
Retention policies that align with compliance rules
Public ChatGPT keeps conversations for 30 days by default—even after deletion. With private deployments, you set the retention clock, not OpenAI. There are multiple ChatGPT Alternatives that provide ability to set a retention policy.
Is ChatGPT Safe From Hackers?
Let’s be clear: no system is bulletproof. Public ChatGPT has had its moments—remember the March 2023 bug where users saw other people’s chat history? Or CVE-2024-27564, the exploit that redirected users to malicious sites, with 10,000+ attempts in one week?
OpenAI invests heavily in security: third-party pen tests, a bug bounty program, and ongoing patches. But a public platform is still a bigger target. Private deployments reduce the attack surface by keeping your AI isolated inside your infrastructure.
The question isn’t “is ChatGPT secure?” It’s “is it secure enough for my industry and risk tolerance?”
Security and Compliance: Meeting Enterprise Standards
Compliance is where things get serious. A single slip here isn’t just a security failure—it’s a regulatory nightmare.
HIPAA and GDPR: Where public falls short
Standard ChatGPT is not HIPAA-compliant. Period. OpenAI itself warns against sharing sensitive data in the free or Plus versions. Only enterprise offerings (ChatGPT Enterprise, Team, Edu, API) provide DPAs for GDPR and BAAs for HIPAA. And those protections still rely on you trusting OpenAI’s servers.
Private deployments, on the other hand, let you enforce custom compliance rules directly: HIPAA guardrails, GDPR data minimization, CCPA opt-outs—on your terms.
Role-based access and audit logging
Enterprise-grade AI isn’t just about encryption. It’s about control. Private setups let you define exactly who sees what, implement least-privilege access, and track every action with immutable audit logs. Public ChatGPT? Limited controls.
Certifications and trust signals
OpenAI’s enterprise products have SOC 2 Type 2, GDPR, and CCPA certifications. Solid, but not customizable. Private deployments can be designed to meet specific industry frameworks like ISO 27001 or custom audit requirements.
Customization and Control: How Much Freedom Do You Have?
AI is not one-size-fits-all. The way you guide and integrate ChatGPT changes the value you get from it.
System prompts: Public ChatGPT has “Custom Instructions,” but they’re often ignored. Private setups let you lock in system messages so the model always behaves in line with your org’s needs.
Tool integration: Public ChatGPT connects only to approved plugins. Private deployments let you build pipelines to your databases, APIs, and apps—without exposing data.
Fine-tuning and embeddings: Private models can be tuned to your jargon, processes, and data. Public ChatGPT offers limited fine-tuning.
Vendor lock-in: Relying only on OpenAI? Risky. Private deployments make it easier to diversify across providers like Anthropic, Mistral, or Llama.
Infrastructure and Cost: The Money Question
Private AI isn’t cheap. A decent self-hosted setup with Llama 3 or Mistral could run $4,000–$30,000 upfront plus power costs. Compare that with the pay-as-you-go pricing of OpenAI’s API.
But here’s the nuance: at scale, private wins. A 13B parameter model can be 9x cheaper to run than GPT-4 Turbo if you’re using it heavily. For startups? Public API is the economical play. For enterprises with constant usage? Private pays for itself.
Industry Fit: Who Needs What?
Healthcare: Must stay HIPAA-compliant. Private deployments are the only realistic option.
Finance: Data residency laws in 135+ countries demand control. Private again.
Retail & HR: Less regulated. Public ChatGPT is often fine for chatbots, surveys, and content generation—speed matters more than airtight security.
Comparison Table
Feature
Public ChatGPT
Private ChatGPT
Data Storage
OpenAI servers, 30-day retention
On-prem or VPC, customizable retention
Data Access
OpenAI staff & service providers
Controlled entirely by your org
Compliance
Basic; not HIPAA-ready
HIPAA/GDPR-ready with custom rules
Certifications
SOC 2, GDPR, CCPA
Configurable to meet ISO, industry-specific
Customization
Limited
Full system prompts, fine-tuning, embeddings
Integrations
Approved plugins only
Full API & database connections
Access Control
Basic
Advanced RBAC
Audit Logging
Limited
Detailed, immutable logs
Costs
Lower upfront
Higher upfront, cheaper at scale
Vendor Risk
High lock-in
Flexible across providers
Conclusion
If your business handles sensitive data, public ChatGPT isn’t enough. It’s convenient, affordable, and powerful, yes—but risky. Private deployments demand higher upfront costs but deliver what enterprises need: control, compliance, and security.
Healthcare and finance? Go private. Retail and HR? Public may be enough. Most organizations will likely end up with a hybrid approach.
The bottom line: AI offers massive upside, but security and compliance are non-negotiable. Choose the setup that protects your data before it’s too late.
FAQs
Q1. Is ChatGPT safe for sensitive business data?
Not by default. Public ChatGPT sends everything to OpenAI servers. Private deployments give you better control and reduce risks.
Q2. What’s the key difference between public and private deployments?
Public relies on OpenAI’s infrastructure. Private runs in your environment, giving you control over storage, access, and compliance.
Q3. Is ChatGPT HIPAA or GDPR compliant?
Public ChatGPT isn’t HIPAA compliant. Enterprise tiers improve compliance, but private deployments remain the safest path for regulated industries.
Q4. How do costs compare?
Public API is cheaper upfront. Private hosting costs more initially but can be significantly cheaper at high usage volumes.
Q5. Can ChatGPT be customized?
Yes. Private deployments allow fine-tuning, deep system prompts, and integration with internal tools—something public ChatGPT can’t match at scale.
AI has become an essential tool for companies looking to boost productivity and spark innovation in today’s fast-paced tech landscape. However, this AI boom has also given rise to a major security concern that keeps corporate security heads and Chief Information Security Officers (CISOs) on edge: Shadow AI.
What is Shadow AI?
Shadow AI occurs when employees use AI tools and applications without their company’s IT team being aware of or approving them. While often adopted with good intentions, these tools can expose organizations to significant risks, including data security breaches, compliance violations, and compromised corporate integrity.
As Itamar Golan, CEO and co-founder of Prompt Security, warns:
“40% of these tools default to training on any data they receive, putting sensitive corporate information at risk.”
This statistic underscores the urgent need for companies to address the Shadow AI problem.
How Common is Shadow AI at Work?
Many organizations underestimate the extent of Shadow AI usage. Golan shares a compelling example:
A financial company in New York assumed they had only a handful of AI tools in use. However, upon investigation, they discovered 65 unapproved programs.
This discrepancy between perception and reality is not uncommon. A survey by Software AG revealed:
75% of office workers already use AI tools.
46% would continue using them even if management disapproved.
These numbers highlight how widespread Shadow AI is and the difficulty companies face in controlling it.
Common Examples of Shadow AI in the Workplace
Shadow AI manifests in various ways across different work environments. Some common examples include:
Generative AI for Content Creation – Employees use tools like ChatGPT or Google Bard for writing emails, reports, or marketing content without official approval.
AI-Powered Data Analysis – Unapproved AI tools process company data, potentially exposing sensitive information to external platforms.
AI-Enhanced Productivity Tools – Workers adopt AI-powered task management or scheduling applications without IT authorization.
Code Generation and Debugging – Developers use AI-assisted coding tools that have not been vetted for security.
Customer Service Chatbots – Teams deploy AI chatbots to interact with customers without ensuring proper data protection measures are in place.
How Shadow AI Affects Security and Productivity
While Shadow AI can enhance individual efficiency, it introduces significant risks at the organizational level.
Security Risks
Data Leakage – Sensitive information may unintentionally be shared with external AI platforms.
Regulatory Violations – Unauthorized AI usage may breach compliance standards such as GDPR, HIPAA, or SOC2.
Exposure of Trade Secrets – Company intellectual property used to train public AI models could be compromised.
Centralized Oversight – IT teams can monitor AI tool usage across the organization, ensuring accountability.
Why Wald Stands Out
Wald offers a holistic approach to AI security:
Human-Like Identification of Sensitive Data – Detects and protects confidential company information.
Intelligent Data Redaction – Wald Context Intelligence™ prevents leaks by replacing sensitive data with secure placeholders.
Identity Masking – Protects both individual and corporate identities, ensuring privacy at every level.
Real-World Impact of Wald
Organizations across industries are seeing significant benefits from using Wald:
“At PayActiv, we use Wald for our marketing needs. It helps us create social posts, email campaigns, and event materials. The platform’s focus on data privacy and access to multiple AI models gives us peace of mind.” — Fatima Afzal, Senior Director, Marketing & Comms, PayActiv
“Wald enables our employees to leverage leading AI models so they can reduce the time they spend on manual tasks. At Suki AI, we aim to increase employee efficiency with cutting-edge AI solutions while maintaining the highest standards of security.” — Jonathan Antonio, Vice President of Infrastructure, Suki
Conclusion: Embracing AI Responsibly with Wald
AI continues to revolutionize the workplace, but organizations must find ways to harness its potential without compromising security. Shadow AI poses a serious challenge, but Wald provides a structured approach to balancing innovation with protection.
By offering secure AI access, ensuring data privacy, and enforcing compliance, Wald enables companies to integrate AI effectively and safely. As AI-driven transformation accelerates, businesses need solutions like Wald to transform Shadow AI from a hidden risk into a controlled and strategic advantage.
AI assistants are everywhere now. In sales. In operations. In compliance workflows. They’re fast, flexible, and transformative. But here’s the problem: every prompt is also an opening. Every response is a potential leak. And attackers know it.
That’s why Gen AI securityis no longer optional. It’s essential. And at the heart of it sits one practice that too many enterprises overlook: data sanitization.
Here is a list of ChatGPT breaches that have happened in the past.
Why Sanitization Matters
Think of data sanitization as the first security checkpoint. Before information even touches an AI system, it gets validated, filtered, and scrubbed. Bad inputs never make it through. Sensitive details get neutralized. The attack surface shrinks dramatically.
The impact is measurable. Organizations with strong sanitization protocols see 76 percent fewer AI-related security incidents. That’s not theory. That’s reality.
Without sanitization, enterprises face more than breaches. They deal with biased outputs, compliance failures, and reputational hits that take years to repair. With it, they gain reliable performance, consistent insights, and a security posture built for scale.
The Bigger Picture of Gen AI Security
Here’s what often gets missed: sanitization doesn’t just protect. It improves AI. Clean data makes models sharper. It reduces drift. It strengthens the trust between humans and machines.
So when leaders talk about Gen AI security, they should be talking about more than firewalls or endpoint protection. They should be asking: “Are we feeding our AI the kind of data that keeps us safe and accurate at the same time?”
How Wald Fits In
At Wald.ai, we see the consequences of skipping this step. Thousands of sensitive data points pass through AI assistants every month inside an average enterprise. Without sanitization, those data points are exposed. With sanitization, they are protected before they can ever leak.
Our approach is built for real-time defense. Contextual filtering keeps meaning intact while scrubbing the risk. Custom rules adapt to industry regulations like HIPAA, GDPR, and CCPA. Encryption and retention controls let enterprises keep ownership of their data. And continuous monitoring ensures nothing slips through unnoticed.
The result: confidence. Enterprises deploy AI assistants without fearing that every prompt could become a headline.
Best Practices for Leaders
The smartest organizations treat data sanitization as strategy, not as a patch. Some of the practices we see working best include:
Input validation: Stop malicious prompts at the front door.
Encryption: Protect data from capture, both in motion and at rest.
Regular audits: Test defenses against emerging threats.
Automation: Reduce errors and scale protections.
Data minimization: Keep only what you need. Less data, less risk.
Access controls: Limit who can touch sensitive protocols.
Continuous monitoring: Spot anomalies before they escalate.
Employee training: Turn staff into active defenders.
None of these are new on their own. But together they form the architecture of modern Gen AI security.
What’s Next
The future of data sanitization will be even smarter. Expect AI systems that automatically adapt to new attack vectors. Immutable audit trails backed by blockchain. Encryption designed specifically for AI-processed data.
Security leaders who act now will be positioned to absorb these advances seamlessly. Those who wait will spend years catching up.
Final Word
The truth is simple. There is no Gen AI security without data sanitization. Not partial protection. Not good-enough defenses. True, scalable, enterprise-ready security begins with clean, controlled, and trusted data.
Leaders have a choice. Ignore sanitization and hope for the best, or treat it as the cornerstone of AI security and build systems that employees and regulators can trust. The enterprises that choose the latter will be the ones that harness AI’s full potential without sacrificing safety.
Prompt Redaction has emerged as a cornerstone of safe AI usage at workplace. This comprehensive guide explores the vital importance of redaction in AI assistants, its far-reaching implications, and best practices for implementation.
Understanding Redaction in the AI Context
Redaction, traditionally associated with censoring sensitive information in documents, has taken on new dimensions in the digital age. In the realm of AI, particularly AI assistants, redaction refers to the sophisticated process of identifying, removing, or obscuring sensitive, confidential, or privileged information before it’s processed, stored, or shared.
Key Aspects of Redaction in AI:
Data Sanitization: Cleansing input and output data of personal identifiers.
Contextual Filtering: Intelligently removing information based on context and relevance.
Format-Agnostic Processing: Applying redaction across various data types (text, images, structured data).
Real-Time Application: Implementing redaction during live interactions with AI assistants.
The Paramount Importance of Redaction in AI Assistants
1. Safeguarding Privacy
AI assistants often handle vast amounts of personal and sensitive data. Redaction serves as a critical line of defense, ensuring that this information is not inadvertently exposed or misused.
2. Regulatory Compliance
With the proliferation of data protection laws like GDPR, CCPA, and HIPAA, redaction helps AI systems maintain compliance, avoiding hefty fines and legal repercussions.
3. Mitigating Bias
By redacting certain types of information, we can prevent AI models from developing or reinforcing biases based on protected characteristics such as race, gender, or age.
4. Enhancing Security
In high-security environments, redaction is crucial for preventing the leakage of classified or sensitive information through AI interactions.
5. Fostering Ethical AI Development
Redaction plays a pivotal role in ensuring that AI systems are developed and deployed ethically, respecting individual privacy and societal norms.
Modern redaction has evolved far beyond simple identification and removal of sensitive information. Today’s advanced algorithms leverage contextual understanding to apply redaction intelligently, preserving the overall meaning and utility of the content while ensuring robust protection of sensitive data.
Key Features of Contextual Redaction:
Semantic Analysis: Understands the context and meaning of the content
Intelligent Masking: Applies redaction without compromising document integrity
Customizable Rules: Allows for tailored redaction based on specific needs
Wald AI, a leading provider in the field of contextual redaction, offers cutting-edge solutions that combine advanced AI with user-friendly interfaces. Their technology ensures that businesses can protect sensitive information while maintaining the value of their documents.
Try Wald Context Intelligence™ for Free: Experience the power of intelligent redaction firsthand. Visit Wald’s website to access a free trial of the state-of-the-art contextual redaction tools and see how they can revolutionize your data protection strategies.
Differential Privacy
This mathematical framework allows for the extraction of useful insights from datasets while maintaining the privacy of individual data points, a concept closely related to redaction in AI systems.
Best Practices for Implementing Redaction in AI Assistants
Comprehensive Data Mapping: Thoroughly understand all data flows within your AI system to identify redaction points.
Regular Audits: Conduct frequent audits of redaction processes to ensure efficacy and identify potential gaps.
Employee Training: Ensure all team members understand the importance of redaction and its correct implementation.
Continuous Improvement: Regularly update redaction strategies based on emerging threats and technological advancements.
Transparency: Be open about redaction practices to build trust with users and stakeholders.
The Future of Redaction in AI
As AI technology continues to advance, so too will the sophistication of redaction techniques. We can expect to see: AI-Powered Redaction: Using AI to improve redaction processes, creating a more dynamic and adaptive system. Blockchain Integration: Leveraging blockchain technology for immutable redaction logs and enhanced auditability. Quantum-Resistant Redaction: Developing redaction techniques that remain secure in the face of quantum computing advancements.
Conclusion: Redaction as a Cornerstone of Trustworthy AI
The importance of redaction in AI assistants cannot be overstated. It’s not merely about protecting sensitive information; it’s about building trust, ensuring compliance, and maintaining the integrity of AI systems. As AI assistants become more integrated into our daily lives and business operations, robust redaction practices will be crucial in harnessing the full potential of AI while safeguarding privacy and security.
By prioritizing redaction and leveraging advanced techniques, we can create more secure, reliable, and trustworthy AI assistants. As we continue to push the boundaries of what’s possible with AI, let’s ensure that we do so responsibly, with redaction as a fundamental pillar of our ethical AI development practices.
Why Traditional DLP Struggles in the Age of Generative AI
Imagine this: you’re swamped at work and need to draft a quick email about a confidential project. Instead of typing it yourself, you turn to a large language model (LLM) like ChatGPT or Gemini. These AI whiz-kids can whip up emails, analyze documents, and even write code in seconds – a real time-saver! But here’s the rub: traditional data leakage protection (DLP) might not be keeping up with this new way of working.
Why? Because traditional DLP relies on old-school methods like data fingerprinting and regular expression matching. These techniques are great for catching things like credit card numbers or employee IDs bouncing around in emails. But they’re not so good at sniffing out leaks happening in a whole new world: prompts sent to LLMs.
The Limits of Traditional DLP Techniques
Data Fingerprinting: Catch Me If You Can
Data fingerprinting works by creating a unique digital signature for sensitive data. But what if the data leak isn’t a copy-paste job? Users can inadvertently paraphrase, rephrase, and even introduce never seen before information in their prompts. Traditional DLP might miss these leaks.
Regular Expressions: Pattern Matching Without Context
Regular expressions are like search filters for specific patterns in text. They’re helpful for spotting basic leaks, but they can’t understand the context of an LLM prompt. Imagine a prompt asking about “Project X,” a secret initiative. A basic filter might miss it, leaving your sensitive data vulnerable.
The Blind Spot of User Intent
Traditional DLP focuses on what data is being sent, not why. But with LLMs, the intent behind a prompt is crucial. A seemingly harmless prompt about “financial data” could end up leaking confidential information. Traditional DLP might not pick up on this.
Why We Need DLP for Generative AI
So, what are we supposed to do? Throw out our DLP altogether? Absolutely not! DLP is still essential for protecting other forms of data leaks. But we need to level it up for the LLM era.
The Future of DLP for AI and ChatGPT
Context is King: Understanding Prompts and Risks
New DLP solutions need to understand the context of prompts sent to LLMs. This might involve analyzing the prompt to identify potential risks and then using data anonymization techniques to mask confidential data.
Beyond Text: Capturing the Intent Behind Prompts
Imagine a DLP system that can not only analyze text but also consider the intent of the prompt. Sensitive topics when leaked can create HR and legal nightmares for companies. These prompts may not contain confidential data but have potent intent and when leaked can cause irreparable harm.
Continuous Learning: Adapting DLP to Evolving AI Use
LLMs are constantly evolving, and so should DLP. The ideal solution should be able to adapt to new ways LLMs are used and identify emerging security threats.
Building the Next Generation of DLP for Enterprises
LLMs are powerful tools that can revolutionize the way we work. However, traditional DLP needs an upgrade to keep pace with this evolving technology. By focusing on context, user intent, and continuous learning, we can build a new generation of DLP that protects sensitive data in the age of LLMs. Remember, data security is an ongoing journey, not a destination. By embracing these advancements, we can ensure that LLMs empower our work without compromising our information security.